Ravelyn Technology Introduces an Inference Compiler for AI Agents and Plans a Large-Scale GPU Buildout
Ravelyn keeps hard reasoning on frontier models and runs routine agent work on purpose-built models. In partnership
Press Release Disclaimer: This is a press release distributed through the XPR Media network. It has not been independently verified by our newsroom.
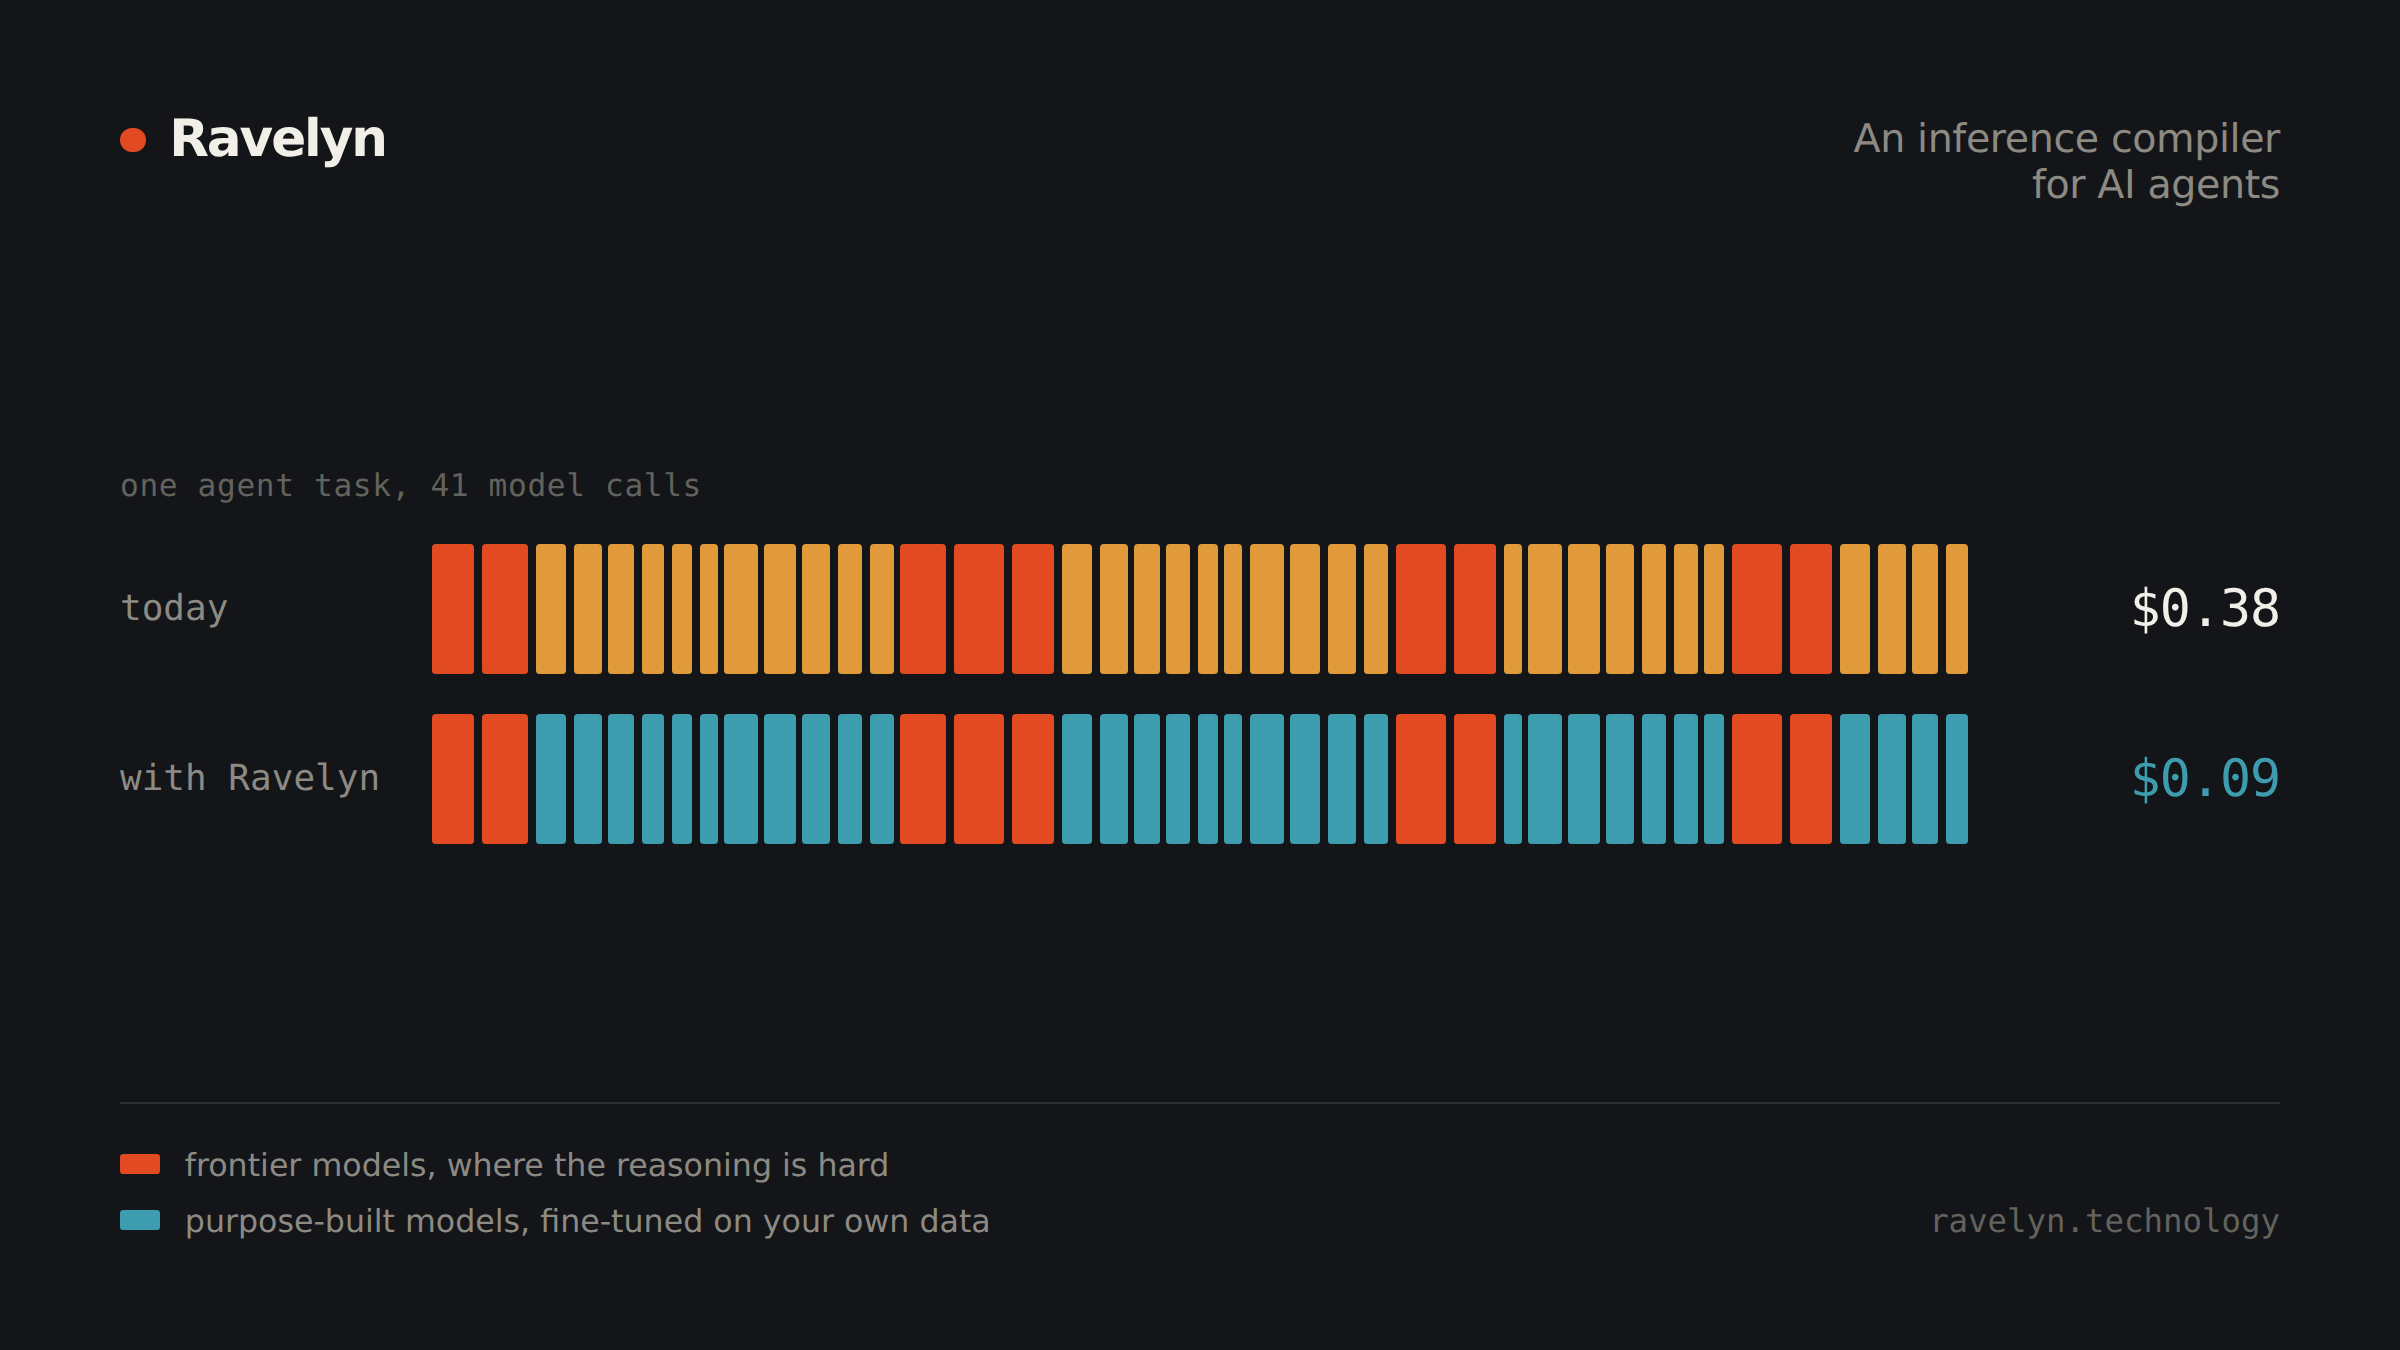

Ravelyn keeps hard reasoning on frontier models and runs routine agent work on purpose-built models. In partnership talks and building its own GPU fleet.
SAN FRANCISCO, CA, UNITED STATES, September 23, 2026 /EINPresswire.com/ — Ravelyn Technology today introduced an inference compiler for AI agents. Ravelyn maps every step an agent takes, keeps the hardest reasoning on frontier models, and runs the routine work on purpose-built models tuned to each customer’s product. The company is in active discussions with major model providers on strategic partnerships and is planning an aggressive buildout of its own GPU infrastructure, including latest-generation rack-scale clusters.
Agents have turned inference into a cost of goods
As agents move into production, one task no longer means one model call. Resolving a support ticket or shipping a code change can take dozens or hundreds of calls, and only a few involve genuinely hard reasoning. The rest is routine: choosing a tool, rewriting a query, ranking results, formatting output. Most teams send nearly all of it to the largest available model, because that is the safe default and proving anything else is good enough takes time nobody has. For many agent companies, inference is now one of the largest lines in their cost of revenue.
How Ravelyn works
Ravelyn brings profile-guided optimization, a staple of compiler engineering, to AI inference. Customers adopt it in four stages and can stop after any of them.
Instrument: a one-line change routes traffic through Ravelyn’s OpenAI-compatible endpoint, adding tracing, failover and per-call cost attribution. This stage is free.
Define correct: customers connect the outcome signal their product already measures, such as tests passing, a ticket staying closed or an agent finishing without a retry. That signal, not a public benchmark, is what Ravelyn optimizes for.
Plan: customers set a budget and service level for an entire task, and Ravelyn picks the right model for every step across the whole trajectory, from frontier models to open-weight models to purpose-built specialists. Every plan is evaluated against the customer’s own success metric before it reaches production.
Compile: for the high-frequency, repetitive steps in a workload, known in compiler terms as hot paths, Ravelyn builds purpose-built specialist models. Each is fine-tuned from a permissively licensed open-weight foundation on the customer’s own data and outcome signals, then served on Ravelyn’s infrastructure at a fraction of the cost.
Every specialist runs behind runtime guards, including confidence thresholds, drift detection, continuous evaluation against the customer’s success metric and per-path rollback. When a guard trips, the request goes to the customer’s chosen frontier model instead.
“Agents turned inference from a feature cost into cost of goods sold,” said Trond Markussen, chief technology officer of Ravelyn Technology. “The instinct is to send everything to the biggest model, because nobody has time to prove anything else is good enough. Ravelyn proves it continuously, against each customer’s own definition of success, and backs off the moment it isn’t. The hard steps stay on frontier models. The routine steps stop paying frontier prices.”
Paid from savings, not from tokens
Ravelyn charges a share of verified savings, measured against a cost and quality baseline agreed in writing before any optimization ships. Savings count only while the customer’s own quality metric holds at or above that baseline. If Ravelyn saves nothing, it charges nothing.
Your data, your models
Each customer’s data trains only that customer’s models, and nothing is pooled across accounts. Specialists are fine-tuned from permissively licensed open-weight foundations, and customers own and can export the resulting weights at any time. Frontier models are used to answer requests, never as a source of training data. Trace retention is configurable from zero to 90 days, with field-level redaction before anything is stored.
Looking ahead
Ravelyn is in active discussions with major frontier model providers on strategic partnerships, including committed-volume agreements that would give Ravelyn customers preferred pricing through authorized channels alongside bring-your-own-key access. Ravelyn is built to put frontier models where they matter most in every agent workload, making agent products profitable enough to keep scaling on frontier models rather than re-platforming away from them to cut costs.
“The fastest way for an agent company to leave a frontier model is an inference bill that forces a rewrite,” said Markussen. “We want the opposite. The calls that reach a frontier model should be the ones that need it, and there should be far more of them as our customers grow.”
Ravelyn is also building its own GPU infrastructure in two layers. A compilation layer, built on latest-generation rack-scale GPU clusters, will continuously fine-tune and refresh each customer’s specialist models as their workloads evolve. A global serving layer will run those models close to customers at low latency. Ravelyn intends to expand aggressively across multiple regions through 2027 and beyond, with the goal of becoming one of the largest dedicated operators of agent inference infrastructure. The company is inviting proposals now from GPU manufacturers’ authorized partners, OEMs, cloud providers, and data center, colocation and power partners, covering purchase, lease and long-term reserved capacity.
Ravelyn is accepting design partners among agent companies in coding, customer support, document processing and sales automation. Qualifying teams receive a free profile of one week of traffic, showing their call-pattern distribution, compilable share and modeled savings.
About Ravelyn Technology
Ravelyn Technology builds an inference compiler for AI agent workloads. Its platform maps agent workloads, routes every step to the most efficient model that meets the customer’s quality bar, and builds purpose-built specialist models from open-weight foundations and each customer’s own data, with guarded fallbacks to frontier models. The company is registered in Delaware. Learn more at ravelyn.technology.
Contacts:
partners@ravelyn.technology (model provider partnerships)
compute@ravelyn.technology (compute and infrastructure proposals)
profile@ravelyn.technology (early access)
press@ravelyn.technology (media)
Alan Gold
Ravelyn Technology
email us here
Visit us on social media:
LinkedIn
Legal Disclaimer:
EIN Presswire provides this news content “as is” without warranty of any kind. We do not accept any responsibility or liability
for the accuracy, content, images, videos, licenses, completeness, legality, or reliability of the information contained in this
article. If you have any complaints or copyright issues related to this article, kindly contact the author above.

Media gallery